Answer:-
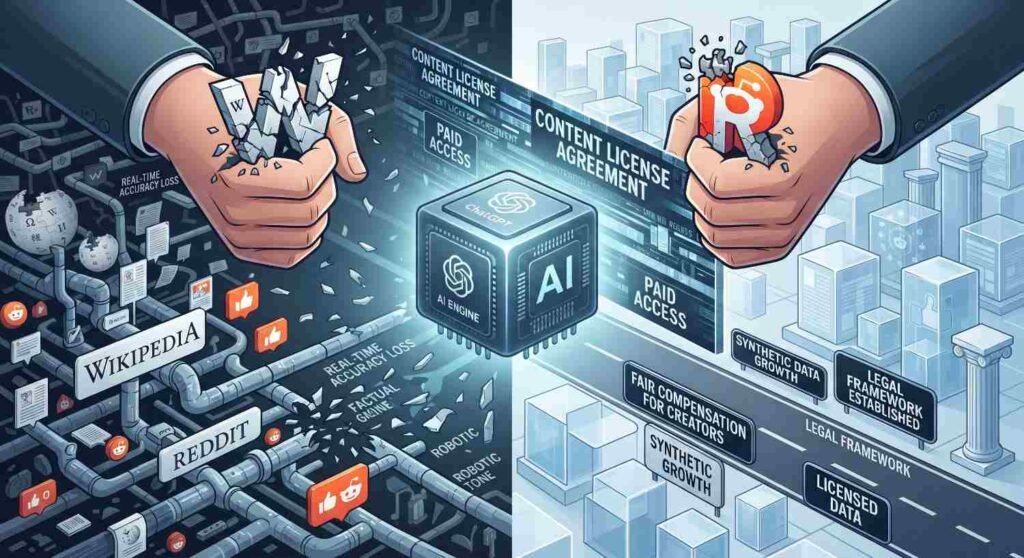
If top websites like Reddit and Wikipedia stop sharing or crawling their data with ChatGPT, it would cause a significant loss in accuracy and performance value for ChatGPT, but at the same time, it would steer the industry toward more secure, legal, and improved data licensing. Both the negative and positive aspects of this scenario are highly important.
Thank you for reading this post, don't forget to subscribe!1. Why ChatGPT Relies Heavily on Data
Large Language Models (LLMs) are not intelligent in a vacuum; their capabilities are built upon billions of web pages, encyclopedic facts, and real human conversations:
-
Wikipedia: Serves as the premier structured, peer-reviewed, and factual knowledge base, anchoring broad topics in history, science, and biography.
-
Reddit: Acts as a massive repository of real human experiences, troubleshooting tips, niche opinions, and colloquial language that formal books miss.
If these sources cut off access, ChatGPT’s knowledge pipeline would lose its freshest and most authentic influx of human context.
2. Negative Impacts (What ChatGPT Would Lose)
If this data were blocked, the immediate consequences would include:
-
Increase in Hallucinations: Without Wikipedia’s peer-reviewed framework as a factual anchor, the model would lose its baseline for truth, driving up rates of incorrect or fabricated answers.
-
Loss of Human Nuance: Without Reddit’s authentic, community-driven discussions, the AI’s tone would become noticeably more robotic, formal, and detached from everyday problem-solving styles.
-
Stale Real-Time Knowledge: Access to breaking trends, fast-moving discussions, and live community feedback would slow down drastically.
-
Higher Operating Costs: OpenAI would be forced to secure expensive, exclusive private licenses for all required information, potentially driving up subscription fees for end-users.
3. Positive Impacts (How the Industry Would Benefit)
Every coin has two sides. A strict data cutoff would also trigger several major positive outcomes:
-
Fair Compensation for Creators: Content creators, writers, and community platforms would finally gain rightful control over their intellectual property, securing proper financial compensation and recognition.
-
Acceleration of Synthetic Data: AI labs would heavily invest in internal synthetic data generation, driving advancements in data privacy and self-improving models.
-
Clear Copyright Frameworks: Such a move would force global regulators and tech giants to establish transparent legal standards and ethical guidelines for AI training data.
-
Quality Over Quantity: AI platforms would shift away from blanket web scraping toward high-quality, expert-verified proprietary databases, elevating the overall utility of the models.
Frequently Asked Questions (Q&A)
Q1: Would ChatGPT completely stop working without Wikipedia and Reddit?
-
A: No. ChatGPT’s core reasoning engine and pre-trained parametric memory would continue to function, but its real-time accuracy, fact-checking capabilities, and conversational warmth would noticeably decline.
Q2: What is the biggest positive outcome of such a block?
-
A: The primary benefit is that original content creators, publishers, and community forums would retain full ownership of their data and could demand fair licensing revenue.
Q3: How would OpenAI adapt to this missing data?
-
A: OpenAI would likely establish direct paid partnerships with major news networks and publishers, rely more on enterprise databases, and expand its use of synthetic data generation.